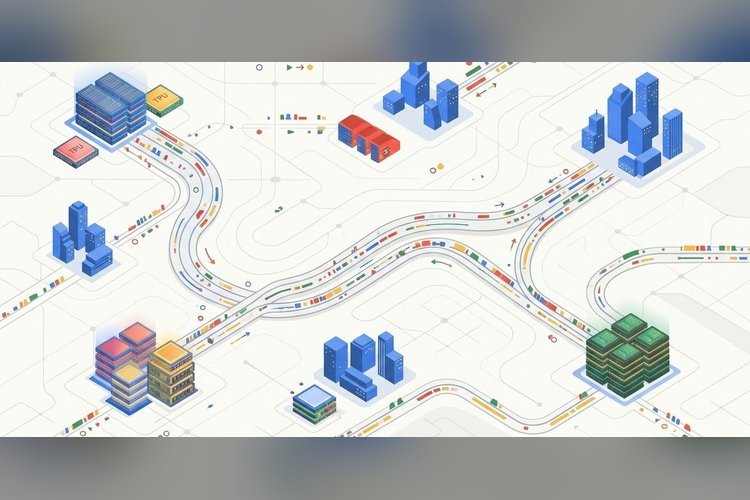
Streaming DiLoCo is now available in MaxText, Google’s open-source JAX-based framework for training large language models. It lets teams pool compute slices in different datacenters, or different metros, without the training stalls that normally hit across slow links. In a benchmark on Qwen3-32B, it delivered a 9.57x speedup over standard data parallelism.
The feature ships in MaxText v0.2.5 on PyPI, in the matching Docker images and on GitHub main.
The problem with one big cluster
State-of-the-art models are usually trained on a single cluster of accelerators sitting together and wired with high-bandwidth links, so every device can sync gradients constantly. Physical and cost limits make it harder to keep growing a single slice.
The alternative is to connect several slices across datacenters. Over a wide-area network, though, standard data-parallel training stalls: the slow transfers can’t be hidden behind computation, and Model FLOPS Utilization collapses. Inside one datacenter, the data center network is fast enough that JAX and XLA often overlap communication with the backward pass. Across sites or congested links, bandwidth drops and latency climbs.
How DiLoCo works
DiLoCo, short for Distributed Low-Communication, was developed by Google DeepMind and Google Research. Rather than syncing at every step, it splits training across M independent groups called learners. Each one runs many local optimization steps before communicating.
After H steps, the learners compute the difference between their current weights and the global weights from the start of the interval. They average those deltas with an all-reduce and apply an outer optimizer, usually SGD with Nesterov momentum, to update the global weights. Communication happens H times less often, typically 1 to 2 orders of magnitude, and quality stays comparable.
What the streaming version fixes
Vanilla DiLoCo still sends the entire model’s deltas at once every H steps. On a thin network that causes a large periodic stall.
Streaming DiLoCo splits the model’s parameters into P separate fragments. Over H steps, each fragment is synchronized exactly once, which keeps the same outer-loop cadence but spreads the traffic out so bandwidth use doesn’t spike. In MaxText, the weight deltas for the scheduled fragment go to sharded syncer workers on the learner host CPUs. They run the all-reduce in the background while the TPUs keep training, then apply the Nesterov update locally and write the fragment back. No central parameter server is needed.
Benchmark results
The team trained Qwen3-32B, which has 64 decoder layers split into P = 65 fragments with H = 65, on two TPU v5p-32 slices. Linux traffic control shaped the inter-slice bandwidth into three regimes: unthrottled, 30 Gbit/s aggregate for moderate congestion and 10 Gbit/s for severe congestion.
Streaming DiLoCo held a flat 5.76 seconds per step, a 9.57x speedup over standard data parallelism, and removed the stall at every H-th step.
A common worry is that letting learners drift apart between syncs hurts quality, especially for mixture-of-experts models where expert routers might diverge. The team compared Streaming DiLoCo with synchronous data-parallel pre-training on two MoE models, Qwen3-30B-A3B and Gemma4-26B-A4B, over 4,000 steps. They report that it preserves quality and even slightly improves validation loss. Momentum in the outer optimizer, with beta at 0.9 and an outer learning rate between 0.3 and 0.7, stabilizes the global trajectory.
How to turn it on
You enable it in a MaxText YAML file or CLI overrides by setting enable_diloco and enable_streaming_diloco to true. The recommended practice is to set both the fragment count and the sync period to the number of layers plus one, so exactly one fragment syncs per step. For Qwen3-8B that’s 37, for Qwen3-30B-A3B it’s 49, and for Qwen3-32B it’s 65.
- diloco_outer_lr of 0.7 and diloco_outer_momentum of 0.9 are the example outer-optimizer settings.
- dcn_diloco_parallelism sets the number of learner islands, for example 2 slices.
- An optional bandwidth limit lets you emulate a constrained WAN on a fast cluster.
What this means for large-scale training
For teams short on a single contiguous block of accelerators, this removes the requirement that all of it sit behind one high-bandwidth fabric. The results so far come from two slices and shaped bandwidth, so real multi-metro runs will be the real test.
Source: developers.googleblog.com