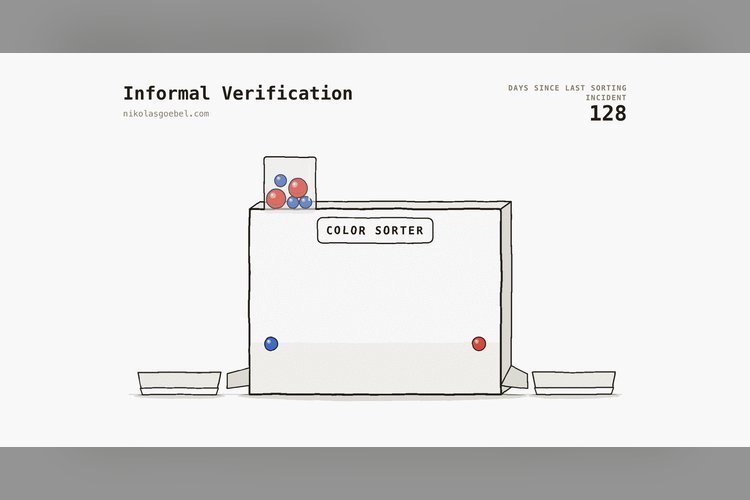
Letting an AI agent change a complex system takes trust, and a new approach called informal verification tries to build that trust with natural-language arguments checked by a fast model. The idea is that formal proofs are sufficient for establishing trust but not always necessary, and that a cheaper informal check can sit beside them.
The approach pairs a System One model named Jev with a tool called autoground. Jev acts as the proof checker, and autoground supplies a lightly structured language, brief, for writing the arguments it checks.
Two kinds of trust
Teams usually build trust from track records. How often did the agent need correcting? How many times did it break production? Those numbers help, but they leave a gap. An agent can close bugs on its own for weeks, and you still can’t tell surgical fixes from a growing pile of tech debt. It can also write clean code and explain it so poorly that nobody wants to give it more freedom.
The missing piece is epistemic trust: believing the system works the way you think it does. The example offered is a machine that appears to sort marbles by color. Inside, it sorts by size, which gives the same result under normal conditions. Feed it a large blue marble and the mismatch shows.
Testing shows how a system behaves. Epistemic trust comes from arguing why it behaves correctly. That means surfacing silent assumptions and breaking big leaps of reasoning into small steps. When many separate points of agreement line up, they are a strong sign the system really matches your mental model. That second kind of trust is what informal verification targets.
Where formal proofs fall short
Agents with access to a proof assistant such as Lean can formalize some arguments and have a deterministic kernel check them. The kernel rarely accepts a flawed argument, and once it accepts one, it won’t change its mind later.
Formalization has its own risks, though. Errors, ambiguities and drift can creep into the translation from the real claim to the formal one. Alan Perlis put it this way: “one can’t proceed from the informal to the formal by formal means.” Questions of this kind came up in 2025 over what the AI-generated Lean proof of Erdős problem #124 had actually established.
An informal argument avoids that translation step. It also works where formalization is impractical, such as showing that software uses a third-party API correctly or that a web page renders according to its CSS. The cost is a higher error rate, caused by ambiguous prose or a lazy reviewer.
What Jev is asked to do
For this to fit fast agent workflows, the checker has to run at scale and without a human. The wish list is short:
- Accept obviously true steps.
- Reject obviously false ones.
- Reject imprecise or ambiguous steps.
- Reject big leaps, even correct ones, so the author splits the argument into smaller pieces.
The last requirement has precedent. The Mizar checker accepts only “obvious inferences” and forces authors to decompose anything larger.
In one test, even Fable 5.2 needed about a minute of reasoning to answer a question, which put it in the non-obvious category. Jev’s answer split almost evenly between true and false. To get Jev to accept the conclusion, a frontier agent has to unpack its own reasoning chain into a tree of sub-claims. Jev then accepts any step a capable language model can follow intuitively, without internal reasoning tokens. It is also multimodal, so arguments can point to diagrams. Running it costs little compared with the agent itself and its other tool calls.
An invoice example of informal verification
The clearest demonstration is a review of a multi-tenant web app. The claim: the endpoint GET /invoices/:id never returns another tenant’s invoice. The argument has four premises tied to code or documentation, followed by three reasoning steps.
The premises cover the tenant middleware, the default scope on the Invoice model, the Rails behavior of applying default scopes, and the controller’s call to find_for_display. Steps one and two pass. Step three says the loaded invoice belongs to the current tenant, and Jev rejects it, because nothing in the premises says find_for_display uses the default scope.
Reading the method confirms the problem. It runs raw SQL through find_by_sql, which ignores the default scope. Any tenant could read any invoice by guessing its id.
Jev didn’t need to know how find_by_sql works, and it didn’t search the codebase. It refused a step that didn’t obviously follow. A human reviewer gets seven concrete claims to compare with their own understanding, instead of one agent’s thumbs-up. The finished proof can also be re-checked cheaply against later revisions with no agent involved.
Known weak spots
Jev makes mistakes a human reviewer might make. Steps near the confidence line between true and false can flip between runs. It also resolves ambiguity the way a fluent reader does. Given “the controller passes the invoice to the serializer after it validates it”, it is 95% confident the controller does the validating, though the sentence allows another reading. A step can pass under an interpretation the author never meant. Jev can also fill in facts it considers too obvious to state.
Consistent terminology and small claims joined by deterministic logic operators are meant to limit these failures, and brief is designed to encourage both.
What to expect from autoground
autoground is an early attempt to turn the idea into a tool, with grounded agentic explanations as the first use case. Its authors don’t claim an informal proof is a guarantee. They argue that proofs also matter for the understanding and trust built along the way, and that informal verification can supply both when no precise specification exists.
Source: nikolasgoebel.com